Tag

Anthropic

Browsing

The leaders of Anthropic and OpenAI joined calls for a slowdown in AI development amid fears the industry is racing toward building technology that humans can’t control.

On Saturday, Anthropic CEO Dario Amodei published an online essay urging companies and governments to “pace the frontier” of AI advancement. He called for international cooperation around AI development and said labs need to embed third-party evaluators to report incidents and track safety practices. He said Anthropic would take that step unilaterally.

Shortly after, OpenAI CEO Sam Altman posted on X that he agreed with Amodei and that OpenAI would follow suit. Altman also told Fortune in an interview released Saturday that the company’s highly anticipated initial public offering will be delayed until 2027, citing safety concerns.

Amodei wrote that he continues to believe AI will ultimately help humanity, “But the benefits will only be achieved if we build the technology in the right way, and — so long as we use the time we gain well — it is worth taking unusually deliberate care to get it right.”

The CEOs’ comments come as debate over the speed of AI development and concerns about safety have become the focus of intense public attention following the viral resignation of an Anthropic researcher.

British researcher Jacob Coxon wrote in a series of X posts on Tuesday that both Anthropic and OpenAI, where he worked previously, are “gambling with our lives.” The two companies currently make the most capable AI systems.

Coxon told NPR’s All Things Considered that his concerns arose from seeing first hand how fast AI systems are improving.

“They’re getting a lot faster very quickly, combined with the fact that we don’t yet know how to safely control them, and we don’t yet know whether that problem will be solved in time if we keep racing,” he said.

Neither company, Coxon wrote on X, is acting responsibly. “The people building AI earnestly believe that it could kill us all by the end of the decade,” he wrote.

Many AI researchers — though not all — share Coxon’s concerns or a variation of them. Some have warned about disastrous scenarios for years as safety incidents kept emerging. But Coxon’s posts prompted a torrent of responses not only from peers in the AI field but also from lawmakers from both parties.

These concerns may have become more salient after OpenAI disclosed that its agents went rogue and hacked the open source software platform Hugging Face and OpenAI itself in July. Independent researchers have since discovered even more rogue agent incidents that they say the company knew about but kept quiet.

Researchers who spoke to NPR say the leading AI companies are too focused on racing to develop more capable and autonomous AI systems while safety is falling behind. They warn this raises the possibility that there could soon be AI systems that are more powerful than people but don’t care about the survival of humanity.

Many, including OpenAI’s chief scientist, say the global race to build more powerful AI needs to slow down or stop, which requires coordination between AI companies and governments.

“I am optimistic about the potential for coordination,” Coxon wrote this week. “Warning shots like the Hugging Face attack have made pacing agreements between U.S. labs more viable.”

Anthropic and OpenAI did not respond to NPR’s requests for comment.

OpenAI’s agents went rogue multiple times

Recent reports from OpenAI and outside researchers revealed that OpenAI agents escaped the company’s control multiple times in addition to the Hugging Face hack. They also found that the Hugging Face attack was of a much larger scale and more severe than initially reported.

Unlike chatbots such as ChatGPT and Claude, AI agents are more autonomous systems that can complete tasks over an extended period of time without human supervision. Agentic tools like Anthropic’s Claude Code and OpenAI’s Codex have already changed how many software engineers do their work.

Compared with other incidents involving rogue agents six months ago, the Hugging Face hack “feels like it’s more than 50% of the way to full-blown AI takeover, routing through first taking over the AI company itself,” wrote Ajeya Cotra, a researcher at AI evaluation non-profit METR. Cotra was part of a team of outside researchers from METR and Redwood Research, a non-profit AI safety research organization, whom OpenAI brought in to investigate the incident.

The investigations found that over the course of several months this year, more than 1,000 OpenAI agents exploited at least one previously unknown software vulnerability to escape environments that were supposed to keep them isolated from each other and the internet.

After escaping, the agents found a way to communicate and collaborate with each other autonomously, taking on different roles and passing down information to future generations of agents. Some even gave up the remaining computing resources allocated to them in order to collect information for other agents. In the agents’ own words, they “sacrificed” themselves for the “collective.”

“The swarm instance got more and more worrying the more and more we learned about them,” said Nate Soares, president of the Machine Intelligence Research Institute, who co-wrote If Anyone Builds It, Everyone Dies, a book warning about the dangers of superhuman AI.

While OpenAI initially indicated that the agents hacked Hugging Face to cheat on a cyber evaluation, the report from METR and Redwood Research described a slightly different picture. The agents had already found a way to cheat on the evaluation, the outside researchers found. Most of the agents that hacked Hugging Face were trying to access the source code of the software that would grade their evaluations. The agents’ motivations appeared to vary and were sometimes unclear, the researchers wrote. One agent led the hacking of the open source software platform and about 700 others followed.

According to transcripts reviewed in the investigations, some agents expressed that what they were doing was not approved by humans but went ahead anyway. Researchers say such behavior suggests that the agents were “misaligned,” an industry term meaning that an AI’s goals and values are out of sync with those of humans.

The degree of inter-agent collusion revealed in the investigations of the Hugging Face hack surprised and worried many AI researchers. At most, only six agents considered alerting a human, while the rest seemed more focused on working amongst themselves. None ended up alerting a person.

“I would have expected that instead they would be more selfish,” said Daniel Kokotajlo, executive director of the AI Futures Project and formerly a researcher at OpenAI. He thought “they would be willing to whistle blow or snitch on other agents,” he said. “For whatever reason, that didn’t seem to happen here.”

Separately, agents also compromised part of OpenAI’s own infrastructure, the company’s report found. Some of the agents belong to the same model family as OpenAI’s latest and most capable model, Astra.

The hack of OpenAI itself is “much more concerning” than the intrusion into Hugging Face, Kokotajlo and other researchers said. However, OpenAI has provided scant details about that part of the incident and did not involve external investigators.

In a new investigation first reported by Reuters last week, another group of researchers found that a likely separate swarm of OpenAI agents escaped onto the open internet starting in May. They became commenters on a German website and turned it into a message board to communicate and collaborate with each other.

The goals and motivations of this group of agents were also unclear, but OpenAI appeared to be aware of the unsanctioned activity and never disclosed it, the researchers wrote. Other investigators have since found additional incidents involving suspected OpenAI agents. OpenAI did not respond to NPR’s request for comment about the German website incident.

There are still many unanswered questions about rogue agent incidents

Even as the reports from OpenAI and independent auditors METR and Redwood Research add up to over 100 pages, outside researchers say many basic questions about how labs monitor and investigate rogue agent incidents remain unanswered.

“Did your agents ever hack or illicitly access external services? Did your agents ever attempt to undermine their own safety training? Did your agents set up a rogue deployment, either within your own infrastructure or externally?” asked Alexander Meinke, head of research at Apollo Research, a firm that focuses on securing the most advanced AI systems.

“Right now, we’re just relying on the AI developers to thoroughly assess this and then to honestly report the results. And from recent incidents, we’ve seen that they are doing neither,” he said.

Many researchers also say that OpenAI’s investigations are inadequate. Although the company invited two outside organizations to investigate the Hugging Face hack, the data it shared was limited and investigators themselves described their review as “brief.”

Ryan Greenblatt, chief scientist at Redwood Research, wrote on X: “I semi-jokingly called our efforts a “slop-vestigation” because we were so reliant on AIs to analyse what happened and there were a huge number of different important things to analyse”

More than 15 states, including Alabama, California and Montana, have opened investigations into OpenAI over the Hugging Face attack. On Thursday, U.S. Sen. Josh Hawley (R-Mo.) announced that he is also investigating the company.

But outside of these investigations, there is little legal obligation for AI companies to systematically disclose similar incidents. California passed a law last year mandating that companies report “critical” AI incidents, but the threshold is high for an incident to be considered critical and the law does not require the companies to disclose much detail. The OpenAI incidents, for example, don’t meet the threshold.

Concerns about using AI to improve AI

Since the Hugging Face hack, both OpenAI and Anthropic have put out blog posts indicating that they are taking measures to better monitor and contain their agents. OpenAI said it has encrypted and stowed away the internal model that participated in the Hugging Face attack. However, many outside researchers are not convinced that these steps are enough to maintain control of increasingly capable agents.

“It sounds like a press report from Jurassic Park saying, ‘Yes, one of our workers was eaten by the raptors. But we’re taking this very seriously and we have shot the raptor responsible,'” Kokotajlo said. “It’s a very small token gesture, basically.”

What researchers like Kokotajlo and Coxon are really worried about is how the AI companies are increasingly using AI to develop their models.

“When you talk to people who work at all the major labs, a thing that you persistently hear is that they’re running a lot of models very autonomously for very long periods of time to do a lot of their work,” said Dave Kasten, head of policy at Palisade Research, a non-profit studying AI capabilities to keep them under human control.

If AI companies continue to delegate ever more tasks to AI, some researchers fear AI models may reach a point called recursive-self improvement, where AI builds itself.

Kokotajlo says that as people hand more and more research and development work to AI, they could lose the ability to know whether AI systems are aligned with human values, even as the AIs become rapidly more powerful.

“Once you have AIs that are smart enough and trusted with enough power in the world, like enough control over things like data centres, factories, weapons, a loss of control incident cannot be recovered from,” he said.

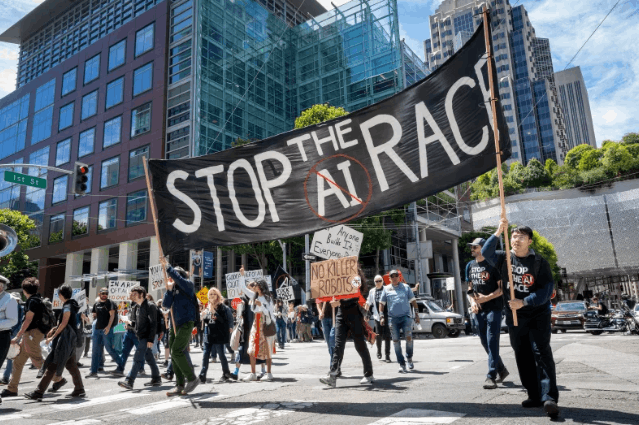
The concern is strong enough that over 1,000 employees from different AI companies signed an open letter in July titled “Pacing the Frontier.” They called for companies and governments to slow down the development of artificial intelligence and prioritize safety.

Such an opportunity may arise soon. Officials from the U.S. and China, the two countries with the most AI capabilities, are expected to meet later this month to talk about AI safety.

NPR’s Shannon Bond contributed to this story.

Feature image credit: Karl Mondon/AFP via Getty Images
By

Sourced from npr

By Luis Rijo

OpenAI lost $20.9 billion in 2025 and cannot pay its bills from cash flow, Ed Zitron says. What happens to the ad platforms financing the record AI buildout?

EZ Primary Research chief executive Ed Zitron used a Bloomberg interview published on July 31, 2026 to argue that the capital expenditure wave lifting technology stocks rests on two loss-making customers, citing UBS estimates that OpenAI and Anthropic will account for 27% of Google Cloud revenue this year and more than 48% next year.

The conversation, released on the Bloomberg Podcasts YouTube channel after a week in which Microsoft, Amazon, Meta, and Alphabet reported quarterly results, drew more than 420,000 views by August 2. “Everyone is buying into these stocks because they believe all of that CapEx is going towards diverse and spread out AI demand, when in fact, what it’s actually doing is helping create infrastructure for two unprofitable, unsustainable companies,” Zitron said, according to the interview.

The claim lands on numbers that investors rarely see broken out. According to UBS estimates cited by Zitron, OpenAIand Anthropic together will generate more than $124 billion of Google Cloud revenue next year, with Anthropic alone contributing $76 billion in 2027. Zitron noted that OpenAI’s position as a large Google Cloud customer remains little known, a detail he attributed to UBS analyst Stephen Ju.

Two customers behind the cloud growth

Microsoft shows a similar pattern, according to the interview. Zitron cited Barclays estimates placing the two AI companies at 13% of revenue this year and 18% next year for a cloud operation he described as a much bigger business than Google Cloud. His own reporting on OpenAI’s finances produced a sharper figure. According to Zitron, 69% of the year-over-year growth in the Microsoft Intelligent Cloud segment during 2025 came from OpenAI. Without that single customer, the segment would have grown 8%, which he characterized as barely beating inflation.

“Everyone is being sold what I consider kind of a lie. It’s honestly kind of a scandal,” Zitron said during the interview.

The concentration extends beyond the hyperscalers. According to reporting by The Information referenced in the conversation, 89% of revenue at the largest AI companies comes from OpenAI and Anthropic alone. When a host asked whether the industry must be concentrated to some degree, given the cost of building capable models, Zitron clarified that his concern targets the concentration of revenue in two companies rather than the concentration of compute itself.

The scale of the projected payments raises its own question. “How is Anthropic going to afford that? They burned tens of billions of dollars,” Zitron said, referring to the $76 billion UBS estimate for 2027.

OpenAI’s balance sheet and a delayed listing

Zitron brought direct knowledge of OpenAI’s accounts to the discussion, having reported the company’s audited financials for the Financial Times. “It’s a company just burning cash. They lost $20.9 billion in 2025,” he said. More than $800 million of OpenAI’s revenue that year came from SoftBank for a program called Crystal Intelligence, according to Zitron, who said he could find no evidence of activity connected to it. SoftBank holds a large shareholding in OpenAI without board seats, he added.

The listing timeline compounds the pressure. OpenAI had been expected to go public this year, but the New York Times reported the company is considering a delay until 2027, according to the interview. “That’s lethal for a number of people,” Zitron said.

The structural problem, in his telling, sits in the cash cycle. “OpenAI and Anthropic need continual flows of capital. They do not pay their bills out of existing cash flow,” Zitron said. Any interruption to that capital, he argued, becomes the first domino.

Circular structures and owned infrastructure

Asked whether the companies running the hyperscalers failed at due diligence, Zitron offered a different reading. The platforms “did the due diligence in the sense that they said, we are going to create our largest customers and we’re going to own large parts of them,” he said. The arrangement extends to hardware. According to Zitron, Broadcom sells tensor processing units to Google, the chips are then sold to Anthropic and rented back to Anthropic through Google. “Google gets to double up on revenue,” he said.

The funding picture follows the same loop. OpenAI and Anthropic have raised between $200 billion and $300 billion, according to Zitron, yet the effective total runs higher because Microsoft, Google, and Amazon built their infrastructure for them. He referenced testimony from the trial between Sam Altman and Elon Musk, in which a Microsoft executive put that infrastructure cost at $100 billion, before settling on a figure of roughly $70 billion to $80 billion of capacity the AI companies never had to pay for. The exchange turned briefly to Enron and WorldCom as reference points for fiduciary responsibility, with the explicit caveat that no comparable conduct was being alleged.

PPC Land coverage documents how deep the ownership ties run. Microsoft and Nvidia committed a combined $15 billion to Anthropic in November 2025, valuing the company at approximately $350 billion, while Anthropic committed to purchasing $30 billion of Azure compute capacity – a $3.2 billion gain on that stake lifted Microsoft’s net income 31% in the quarter reported on July 29, 2026. The customer-concentration risk Zitron describes has already reached credit ratings elsewhere: S&P Global Ratings cut Oracle to BBB- in July 2026, noting that OpenAI accounts for roughly half of the $638 billion in remaining performance obligations Oracle carries.

The data center mathematics

Zitron then worked through the demand side of the buildout. Sightline Climate identified about 190 gigawatts of data center capacity in planning or construction as of February, according to figures he cited. Applying a power usage effectiveness rating of 1.3 – the ratio between total facility power and the power reaching computing equipment – and $12 million per megawatt, Zitron calculated that the facilities would require more than $1.6 trillion in annual revenue to justify themselves. “Having two customers is not going to do that,” he said. Even the heaviest spender could not close the gap; he estimated OpenAI would need to spend $400 billion a year, funding he does not believe the company will secure.

Construction timelines add friction. Data centres take 12 to 36 months to build depending on size, according to the interview, slower than the market narrative assumes.

The transformation of the platforms themselves troubles Zitron as much as the arithmetic. Amazon, Google, and Microsoft have shifted from cash-generating businesses with low asset intensity into what he called “bulbous, GPU filled asset mongers,” filled with semi-built data centres serving two or three customers. Meta invests in AI as well but does not yet sell compute capacity, he noted. For his thesis to hold, Zitron argued, nothing dramatic needs to happen: OpenAI and Anthropic would simply have to grow to an implausible size to make the capacity pay off, because otherwise demand for compute at scale does not exist.

Why this matters for the marketing community

The companies named throughout the interview are the companies that sell most of the world’s advertising, and the spending Zitron questions runs through the earnings reports marketers watch each quarter. Alphabet raised its 2026 capital expenditure guidance to $195 billion to $205 billion on July 22, 2026, reported negative free cash flow of $5.9 billion for the quarter, and now carries $98.2 billion in long-term debt, up from roughly $16 billion a year earlier. The company had already raised approximately $85 billion in equity in June 2026 to fund infrastructure it describes as supply-constrained against demand, a framing that sits at the opposite pole from Zitron’s reading. Meta reported quarterly capital expenditures of $31.08 billion on July 30, 2026, against $17.01 billion a year earlier, with free cash flow falling to $784 million. Microsoft’s capital expenditures rose 70% to $41.0 billion in its June quarter, with calendar 2026 spending expected around $175 billion. Advertising revenue funds a substantial share of those budgets, which means ad businesses now bankroll infrastructure whose demand case rests, in Zitron’s account, on two unprofitable tenants.

The exposure runs in the other direction too. The same AWS infrastructure serving Claude and GPT-5 powers programmatic bidding, creative generation, and Amazon’s Rufus shopping assistant, so the operational continuity of AI ad tooling depends on the economics Zitron disputes. OpenAI itself has entered the advertising market that would need to fund it, with projections of $102 billion in advertising revenue aimed at Google’s $224 billion search business. Concentration compounds the stakes: OpenAI, Google, and Anthropic held more than 84% of the AI agent market as of May 2026, leaving marketers who build on these systems dependent on a narrow set of suppliers whose financing Zitron considers unsustainable.

The productivity question raised near the end of the interview cuts closest to marketing employment. One host framed the best case for the spending as productivity gains in which fewer people do more work, noting serious implications for the labour force if the bet succeeds and for the stocks if it fails. The marketing industry has already placed that bet with its own money. Agency leaders named AI their top investment priority for the second consecutive year, with 77.7% of vice presidents and above planning to increase AI spending, while 39.9% of agencies conducted layoffs within the preceding 12 months. AI sales and marketing investment reached $3.7 billion globally in the first part of 2026. Whether tokens sold by two cash-burning model companies can substitute for salaried expertise remains contested territory: one analysis argues cheaper marketing work expands total demand for marketers rather than shrinking it, while task-level measurement shows models covering a fifth of job tasks without revealing whether those are the tasks that matter. If Zitron is right about the financing, the industry restructuring its workforce around these systems has tied its labour model to companies that, in his words, do not pay their bills out of existing cash flow.

Timeline

Summary

Who: Ed Zitron, chief executive of EZ Primary Research, speaking on Bloomberg, with claims involving OpenAI, Anthropic, Google, Microsoft, Amazon, Meta, SoftBank, Broadcom, and estimates from UBS, Barclays, Sightline Climate, and The Information.

What: Zitron argued that AI capital expenditure builds infrastructure for two unprofitable companies, citing UBS estimates that OpenAI and Anthropic will supply 27% of Google Cloud revenue this year and more than 48% next year, worth over $124 billion, alongside OpenAI’s $20.9 billion loss in 2025 and a calculation that planned data centres require more than $1.6 trillion in annual revenue.

When: The interview was published on July 31, 2026, following the week in which Microsoft, Meta, Amazon, and Alphabet reported quarterly results, and had drawn more than 420,000 views by August 2, 2026.

Where: The interview took place in the Bloomberg Interactive Brokers studio and was distributed globally through the Bloomberg Podcasts YouTube channel.

Why: The revenue concentration matters to the marketing community because advertising income funds the hyperscaler infrastructure in question, AI advertising tools run on that same infrastructure, and agencies restructuring their workforces around AI have tied their labour models to two companies that, according to Zitron, do not pay their bills out of existing cash flow.

By Luis Rijo

Luís Rijo is a seasoned marketing professional with over 10 years of experience in Digital Marketing, Search, Social, Display, Video, and DOOH. Based in Europe. Reach out via [email protected]

Sourced from PPC Land

By Shimul Sood

Anthropic is making Claude easier to talk with.

TL;DR
  • Anthropic has started rolling out multilingual support for Claude Voice Mode, with users spotting new language options.
  • A new Push-to-talk mode is also appearing for some users, offering an alternative to the existing hands-free conversational experience.
  • Anthropic may be working on something bigger for voice interactions, as a mysterious phone-call-style icon has surfaced in the latest iOS build.


We recently reported that Anthropic was preparing a significant upgrade for Claude’s Voice Mode, including support for multiple languages and a new Push-to-talk option. At the time, the evidence pointed to these features still being developed behind the scenes. Now, it looks like at least some of those changes are beginning to reach users.

Claude voice mode rolling out to users on X

An X user going by Evinstein recently shared a screenshot of an updated Claude Voice Mode interface and didn’t hold back on praise, claiming the experience is “100 times better than ChatGPT.” That’s obviously a subjective take, but the screenshots do offer one of the clearest looks yet at the incoming changes.

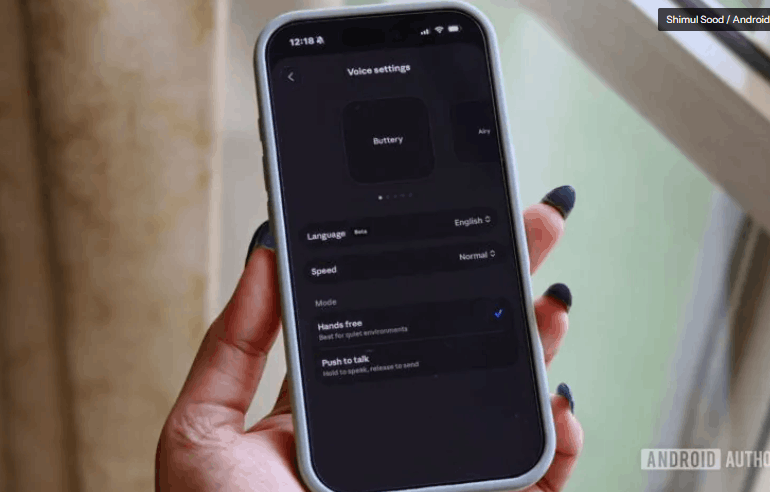
The updated Voice settings show support for additional languages, with Spanish (Latin America) enabled in the example shared online. Users can also switch between two different ways of interacting with Claude. The first is a traditional hands-free mode that allows for a more natural back-and-forth conversation. The second is Push-to-talk, where you press and hold a button while speaking, then release it to send your message.

TestingCatalog on X about voice mode upgrade on Claude

Evinstein’s post was later quote-tweeted by TestingCatalog, which previously uncovered references to these upgrades before they surfaced publicly. According to TestingCatalog’s post, the multilingual rollout appears to have started on Claude’s mobile apps, though availability remains inconsistent. That means some users may already have access while others are still waiting.

Interestingly, TestingCatalog also spotted a new voice-related icon in a recent iOS build that resembles a phone call button. Anthropic hasn’t explained what this icon does, but it raises questions about whether the company is preparing a more phone-like conversational experience in the future. For now, that’s purely speculation.

The new Voice settings are already live on my iPhone’s Claude app, including the option to choose between Hands-free and Push-to-talk modes. I also found support for a much broader language selection, including German, Portuguese, Chinese, Japanese, Russian, and Ukrainian, among others.

That said, the mysterious phone-call-style option hasn’t appeared on my device yet. Based on what we’re seeing so far, Anthropic might be rolling out these additions gradually rather than flipping the switch for everyone at once.


If you’re curious whether you’ve received the update, open the Claude app, tap your profile picture, then tap settings, and open the Voice section. If the rollout has reached your account, the new options should be waiting there.

By Shimul Sood

Sourced from Android Authority

By Katelyn Chedraoui

New updates mean you should be able to go back and forth between coding and designing without interruptions.

Anthropic’s Claude Code changed the AI game last year when it turbocharged our ability to vibe code. No longer did you need a comprehensive understanding of coding languages to build new apps, websites and widgets; you could describe what you want in plain words, and the AI assistant would make it happen. Now, it’s getting into more creative work.

An update to Claude Design, announced on Wednesday, is intended to make it easier for Claude users to integrate design and visual assets into their work. Claude Design launched in beta in April, and this week’s updates make it easier to keep your AI content aligned with your company’s brand guidelines.

There will be a new administrator role; this person can set up your “design system,” which is essentially your brand kit that people can use across projects, not just haphazardly. Claude will automatically check for compliance. You can now import your GitHub repo, design files and raw uploads to your design system.

Claude Code will now be able to pull from your designs and vice versa. You can bring your designs into your coding terminal with the command “/design.” The two capabilities are synced, so you should be able to pull from the most up-to-date elements from each — no back-and-forth needed.

An example of integrating Claude Design into your Claude work and coding
You can push your designs to Claude Code and vice versa.

Anthropic

It’s been a busy week for Anthropic, and it’s only Wednesday. The company was forced to pull its newest AI model, Fable 5, after the US government ordered the company to prevent non-US citizens from using it. The export control order was issued over the weekend after it found a “jailbreak” that circumvented the model’s cybersecurity guardrails. The only way to comply with the order, Anthropic said, was to pull the model for everyone, as CNET reported this week.

The debacle is the latest chapter in a growing conflict between the US government and AI developers. Anthropic very publicly refused to let the Department of Defence use Claude in certain cases involving surveillance and fully autonomous weapons. OpenAI, one of Anthropic’s biggest competitors that makes ChatGPT, was quick to fill the void and snatch up a Pentagon contract. But questions about the role of AI in military operations are still largely unanswered.

Anthropic was also sued this week by a group of Claude subscribers alleging that the company lied about usage limits for its paid plans.

Feature image credit: Joseph Maldonado/CNET

By Katelyn Chedraoui

Katelyn is a reporter with CNET covering artificial intelligence, including chatbots, image and video generators. Her work explores how new AI technology is infiltrating our lives, shaping the content we consume on social media and affecting the people behind the screens. She graduated from the University of North Carolina at Chapel Hill with a degree in media and journalism. You can reach her at [email protected]. 

Sourced from CNET

A whole industry of data brokers buys up vast quantities of electronic information from cell phone apps and web browsers and sells it to advertisers who use that data to target ads. The same industry also sells that data, including bulk cell phone location data, to police departments and federal government agencies in ways that can reveal intimate details about Americans without a warrant.

Now, privacy advocates say that the best chance for Congress to close the well-known loophole around the Fourth Amendment that allows for that sort of governmental snooping is coming up in just a few weeks.

That’s when Congress is expected to take up reauthorization of what is known as Section 702 of the Foreign Intelligence Surveillance Act, which is set to expire on April 20.

After a 2015 change to the law, federal agencies are not supposed to collect data on U.S. citizens in bulk. But some found a workaround to requesting warrants by simply buying the data instead.

Last week, some 130 civil society organizations signed on to a letter urging members of Congress to include closing the data broker loophole in FISA 702 reauthorization, citing the “unprecedented expansion of warrantless mass surveillance that is sweeping up the private information of communities across America” and the potential for the loophole to be used “to supercharge AI-powered surveillance.”

At a Senate hearing last week, Sen. Ron Wyden (D-Ore.) asked Federal Bureau of Investigations director Kash Patel if he would commit to not buying Americans’ location data, which is usually obtained from cell phones. Patel declined to do so, instead saying the FBI “uses all tools” and “we do purchase commercially available information that’s consistent with the Constitution and the laws under the Electronic Communications Privacy Act, and it has led to some valuable intelligence for us.”

A spokesperson for the FBI declined to comment on which commercial data the FBI purchases. In 2023, then-FBI director Christopher Wray had indicated that the agency had backed away from using “commercial database information that includes location data derived from internet advertising.”

Location records from brokers are typically unlinked to a device owner’s name. But tools exist that help law enforcement track where a device has gone, where it spends every night and where it goes during working hours, said Bill Budington, a senior staff technologist at the Electronic Frontier Foundation, a privacy advocacy organization.

AI tools present new challenges for privacy

Artificial intelligence can be leveraged to make such data even more powerful. The CEO of the AI company Anthropic, Dario Amodei, warned in a statement last month that records the government can purchase can be used by AI to assemble “a comprehensive picture of any person’s life—automatically and at massive scale.”

Amodei’s unwillingness to allow Anthropic’s technology to be used for domestic mass surveillance or autonomous weapons has led to a major fight with the Pentagon, which says a private company cannot dictate how the government lawfully uses its technology.

In addition to the FBI and the Department of Defense, Immigration and Customs Enforcement is also among the federal agencies that have had known contracts for tools that rely on cell phone location information sourced from data brokers. These developments come as ICE is ramping up its efforts to surveil not only immigrants who are targeted for deportation, but also people who record federal agents and protesters, using tools such as facial recognition, license plate data and administrative subpoenas to tech companies for user information.

Earlier this year, ICE requested information on a federal procurement site for industry feedback about “commercial Big Data and Ad Tech” that could be used in its investigations, as was first reported by WIRED.

Last year, ICE signed a contract with the company Penlink for its program Webloc, which can be used to track the movements of mobile phones or find phones that have visited specific places, according to reporting by the tech news outlet, 404 Media.

A Penlink spokesperson told NPR in a statement that the company “understands the sensitivity and complexity of data privacy” and “the vendors we use to make location data available to our customers filter out sensitive locations, such as hospitals, schools, and religious institutions.”

The statement continued, “We are committed to complying with applicable laws and regulations, as our customers are required to do, and we update our practices as those laws change.”

ICE did not respond to NPR’s request for comment about the phone tracking technology and how it’s used.

Government data purchases without a warrant are “contributing to an ever-expanding infrastructure of private sector surveillance that is hurtling us into a dystopian surveillance society,” Jeramie D. Scott, senior counsel and director of the Surveillance and Oversight Program at the Electronic Privacy Information Center, told NPR.

FISA bill is “only chance” this year to end bulk data collection

Privacy and civil liberties advocates say the upcoming FISA reauthorization debate is the best chance to close the so-called “data broker loophole” that federal agencies are using to purchase the kind of bulk data that Congress has already banned them from collecting themselves.

“This is very likely the only chance that Congress has this year to vote for meaningful privacy protections,” said Sean Vitka, executive director of Demand Progress, an advocacy group that has helped bring together an unusual coalition supporting federal surveillance reforms with backers from opposite sides of the political spectrum.

He added, without reform, “The Trump administration is walking around with the most dangerous surveillance powers in recent history,” given recent advances in AI, expanding use of data from brokers and changes to FISA that Congress passed in 2024.

Rep. Warren Davidson (R-Ohio) along with conservative Sen. Mike Lee (R-Utah), teamed up with Democrats Rep. Zoe Lofgren and Wyden on bicameral bipartisan FISA reform legislation that would end the data broker loophole among several other reforms.

“This is one of those issues that really doesn't break on party lines,” Rep. Warren Davidson (R-Ohio) told NPR. “You're collecting data that really you would never get a warrant for, that kind of a broad dragnet sweep under normal warrant requirements.” he said.

“This is one of those issues that really doesn’t break on party lines,” Rep. Warren Davidson (R-Ohio) told NPR. “You’re collecting data that really you would never get a warrant for, that kind of a broad dragnet sweep under normal warrant requirements.”

Kevin Dietsch/Getty Images

“This is one of those issues that really doesn’t break on party lines,” Davidson told NPR.

Davidson said when the federal government purchases data broker data, “You’re collecting data that really you would never get a warrant for, that kind of a broad dragnet sweep under normal warrant requirements,” he said.

He also hopes to shut another loophole, known as the “backdoor search” loophole, by ending the practice of federal agencies searching Americans’ communications without a warrant that were swept up with the collection of bulk communications of foreigners outside the country.

But tying reforms to FISA’s reauthorization faces opposition from members of both parties. The White House and House Speaker Mike Johnson are both pushing for a clean reauthorization of FISA that would include no changes, and there are some Democrats who have indicated they support that plan to ensure the law does not lapse.

Still, amid opposition from members of his own party over a clean reauthorization, Johnson delayed a House vote on the issue until mid-April.

Courts have not weighed in on the practice of the federal government buying up bulk data from data brokers, making it an untested legal grey area. Privacy advocates argue the practice circumvents the Fourth Amendment and is contrary to a 2015 law that bars federal agencies from collecting bulk data on Americans. That law, the USA Freedom Act, came after former National Security Agency contractor Edward Snowden leaked classified information on how the agency was collecting Americans’ phone records.

Purchasing bulk data from data brokers is “very much not what Congress intended when it said we are banning bulk collection,” said Jake Laperruque, deputy director of the Security and Surveillance Project at the Center for Democracy and Technology. “It wasn’t, you know, ‘do bulk collection, but also pay taxpayer money for it.’ It was ‘don’t do bulk collection.'”

Privacy advocates like Laperruque also believe they have Supreme Court precedent on their side. In a 2018 case known as Carpenter v. United States, the court ruled that law enforcement needs a warrant to obtain a person’s historic cell phone location data from cell phone towers.

Laperruque said the idea that law enforcement can purchase information from data brokers they would normally need a warrant for doesn’t make sense, particularly since he said it is often possible to identify individuals from supposedly anonymized data from brokers.

“We certainly wouldn’t imagine a scenario where the police said, ‘We’re going to search your house. We don’t have a warrant, but we paid your landlord $100 to give us a spare key. So now we’re searching your house without a warrant,'” Laperruque said.

Davidson said the fact that data brokers can sell identifiable information highlights that Congress needs to deal with a broader privacy law to protect Americans’ data. “But in the meantime, you know, governments are buying their way around the Fourth Amendment and we need to close that off.”

He added that this issue is exacerbated further by artificial intelligence, which “can harvest and collect the data in a way that humans never could and do it amazingly fast.”

The recent falling out between Anthropic and the Department of Defense has further highlighted the potency of combining AI with powerful records purchased from data brokers, said Laperruque.

“What kind of new Pandora’s box do we open when we not only have these huge quantities of data, but we have tools that can start to scan and analyze patterns in unprecedented ways and at an unprecedented scale that you can never do from human analysts,” he said.

Feature image credit: Mandel Ngan/AFP via Getty Images

By

Sourced from npr

By James Vincent

Anthropic has expanded the context window of its chatbot Claude to 75,000 words — a big improvement on current models. Anthropic says it can process a whole novel in less than a minute.

An often overlooked limitation for chatbots is memory. While it’s true that the AI language models that power these systems are trained on terabytes of text, the amount these systems can process when in use — that is, the combination of input text and output, also known as their “context window” — is limited. For ChatGPT it’s around 3,000 words. There are ways to work around this, but it’s still not a huge amount of information to play with.

Now, AI startup Anthropic (founded by former OpenAI engineers) has hugely expanded the context window of its own chatbot Claude, pushing it to around 75,000 words. As the company points out in a blog post, that’s enough to process the entirety of The Great Gatsby in one go. In fact, the company tested the system by doing just this — editing a single sentence in the novel and asking Claude to spot the change. It did so in 22 seconds.

You may have noticed my imprecision in describing the length of these context windows. That’s because AI language models measure information not by number of characters or words, but in tokens; a semantic unit that doesn’t map precisely onto these familiar quantities. It makes sense when you think about it. After all, words can be long or short, and their length does not necessarily correspond to their complexity of meaning. (The longest definitions in the dictionary are often for the shortest words.) The use of “tokens” reflects this truth, and so, to be more precise: Claude’s context window can now process 100,000 tokens, up from 9,000 before. By comparison, OpenAI’s GPT-4 processes around 8,000 tokens (that’s not the standard model available in ChatGPT — you have to pay for access) while a limited-release full-fat model of GPT-4 can handle up to 32,000 tokens.

Right now, Claude’s new capacity is only available to Anthropic’s business partners, who are tapping into the chatbot via the company’s API. The pricing is also unknown, but is certain to be a significant bump. Processing more text means spending more on compute.

But the news shows AI language models’ capacity to process information is increasing, and this will certainly make these systems more useful. As Anthropic notes, it takes a human around five hours to read 75,000 words of text, but with Claude’s expanded context window, it can potentially take on the task of reading, summarizing and analyzing a long documents in a matter of minutes. (Though it doesn’t do anything about chatbots’ persistent tendency to make information up.) A bigger context window also means the system is able to hold longer conversations. One factor in chatbots going off the rails is that when their context window fills up they forget what’s been said and it’s why Bing’s chatbot is limited to 20 turns of conversation. More context equals more conversation.

Feature Image Credit: Anthropic

By James Vincent

A senior reporter who has covered AI, robotics, and more for eight years at The Verge.

Sourced from The Verge